The Counter X Blog

Deep dives into software, hardware, and the ideas reshaping how we build things.

Archives (page 7 of 12)

Why Most People Stare at Dumps Like They’re Hieroglyphics

Why Most People Stare at Dumps Like They’re Hieroglyphics

You’ve been there. The system crashed. The screen went blue, or the process just vanished from the task list like a witness in a mob trial. A memory dump file sits on your disk, taunting you with its opaque binary silence. Most engineers crack it open, see a wall of hex addresses, and immediately close the file—convinced the answer must be somewhere else. Anywhere else.

Here’s the thing: that dump file is a crime scene. And right now, you’re the detective who doesn’t know how to read blood spatter. Memory dumps aren’t just forensic artifacts for Microsoft support engineers or security researchers with three letters after their names. They’re the raw, unfiltered truth of what your system was doing the millisecond it all went sideways. Learning to read them means you stop guessing and start knowing.
Code on a dark terminal screen representing memory analysis

What a Memory Dump Actually Is

A memory dump is a snapshot—either partial or complete—of the system’s RAM at the moment of a crash. When Windows hits a fatal error (bug check, STOP error, blue screen), the kernel captures what it can based on configuration and writes it to disk. Linux does something similar with kdump and kexec. The file extension varies: .dmp, .mdmp, vmcore. The principle doesn’t.

There are different flavors. A minidump is compact—it carries thread stacks, loaded module lists, and basic context. A kernel dump includes kernel memory. A full dump grabs everything: user space and all. Most production systems are configured for minidumps because nobody wants a 64GB file eating disk space after every crash. But if you’re hunting a bug that crosses the user-kernel boundary, you’ll want more than the minimum.

Configuration Matters

On Windows, check your Startup and Recovery settings. The CrashDumpEnabled registry value under HKEY_LOCAL_MACHINE\SYSTEM\CurrentControlSet\Control\CrashControl determines what gets written. On Linux, your kdump configuration and crashkernel reservation size dictate whether you even get a dump at all. No reservation, no dump. Configure first, crash second.

Getting Your Hands Dirty: Generating a Useful Dump

Sometimes you don’t wait for a crash. You force one. Sysinternals procdump lets you capture a process dump on demand or based on conditions—CPU spikes, handle leaks, hung windows. On Linux, gcore does similar work. For kernel-level investigation, NotMyFault from Sysinternals intentionally crashes the system so you can test your dump pipeline. Sounds reckless. It’s responsible.

If you’re dealing with an intermittent issue that won’t reproduce on your machine, make sure crash dumps are enabled on the affected system. No dump means you’re flying blind, relying on logs that tell you what happened before the crash but not what caused it. There’s a reason flight recorders survive the plane.

The Anatomy of a Dump File

Before you can read a dump, you need to understand what’s inside it. The file starts with a header that identifies the dump type, the operating system version, and the bug check code. This header is what debugging engines parse first—it tells them how to interpret everything that follows.

After the header comes the actual memory content. In a minidump, this is a compressed and filtered subset. In a full dump, it’s essentially a linear image of physical memory. The debugging engine maps virtual addresses to this content using the page tables stored in the dump itself. If those page tables are corrupt or missing, addresses won’t resolve, and you’ll see a lot of “unable to read memory” errors. That’s not a tool problem. That’s your dump telling you something was already wrong before the crash.
Multiple screens displaying technical data and system diagnostics

Reading the Tea Leaves: Key Sections That Matter

The Bug Check Code

On Windows, this is your starting point. The STOP code—like 0x0000007E (SYSTEM_THREAD_EXCEPTION_NOT_HANDLED) or 0x00000050 (PAGE_FAULT_IN_NONPAGED_AREA)—tells you the category of failure. The parameters that follow narrow it down. Parameter 1 in a 0x50 dump is the referenced memory address. Parameter 2 tells you if it was a read or write operation. The documentation for each bug check is on Microsoft’s debugger documentation, and it’s one of the few references worth reading cover to cover.

The Stack Trace: Your Best Friend

The stack trace is where the story lives. When you run !analyze -v in WinDbg, it automatically walks the stack of the crashing thread. Each frame represents a function call. The top of the stack is where execution stopped. The frames below show the call chain that got you there.

Here’s what most people miss: the crashing frame isn’t always the guilty frame. A null pointer dereference in DriverX::HandleRequest might be caused by DriverX::Initialize failing to set up a structure three seconds earlier. The crash is the symptom. Walk the stack. See who called what. Check the parameters passed between frames. k gives you the stack. dps lets you dump stack memory with symbol resolution. Use both.

Disassembly: Where the Ghost Lives

Symbols get you function names. Disassembly gets you the actual instruction that failed. Run u on the instruction pointer address, and you’ll see the exact assembly opcode that triggered the exception. Was it a mov trying to read from a null pointer? A call through a vtable that got corrupted? The disassembly tells you what the CPU was actually attempting when everything fell apart.

If you don’t have symbols—and sometimes you won’t—the disassembly is all you have. Learning to read x86 or ARM assembly is non-optional if you want to do this work for real. You don’t need to write it. You need to read it. There’s a difference.

Common Patterns and What They Signal

After you’ve read enough dumps, patterns emerge. Here are a few that show up repeatedly:

  • A single reference count going to zero too early: Look for ObDereferenceObject in the stack. Something freed an object that was still in use. The subsequent access violates because the memory has been reclaimed or repurposed.
  • Stack overflow in a driver: The stack base address will be suspiciously close to the current stack pointer. Recursive calls or excessively large local buffers are the usual suspects.
  • Memory corruption across pool boundaries: If you see a crash in a pool allocation routine like ExFreePoolWithTag and the caller swears they passed the right pointer, something stomped on the pool header earlier. Use !pool to inspect surrounding allocations. The culprit is often in a different driver entirely.
  • IRQL_NOT_LESS_OR_EQUAL with a user-mode address: Something tried to access pageable memory at an elevated IRQL. This almost always means a driver is touching user buffers without proper handling at DISPATCH_LEVEL or above.

Tools of the Trade

WinDbg remains the standard for Windows kernel debugging. Get it from the Windows SDK. Learn the extensions: !process, !thread, !irql, !pool, !vm. These are not optional. They are the interface between you and the dump.

For Linux, crash is your primary tool. Paired with gdb for user-space dumps and makedumpfile for filtering vmcore content, it gives you comparable capability. The learning curve is steep. The documentation is scattered. Learn it anyway.

GDB itself is indispensable for user-space core dumps on any Unix system. Run gdb /path/to/binary /path/to/core, then bt full for a detailed backtrace, info registers for CPU state, and x/20x $rsp to inspect the stack. The GDB documentation is thorough if you take the time to read it.
Person working on code in a dimly lit technical workspace

Symbols: The Difference Between Guessing and Knowing

A dump without symbols is like a map without labels. You can see terrain, but you can’t name a single street. Microsoft makes public symbols available through their symbol server. Configure WinDbg with .sympath srv*C:\Symbols*https://msdl.microsoft.com/download/symbols and most Windows modules will resolve. Third-party drivers won’t—not unless the vendor provides them, which almost none do.

When symbols are missing, you’ll see module names followed by offsets like mydriver+0x1a3f. That offset is a specific instruction within the driver binary. If you have the binary (and you should—find it in the dump’s loaded module list), you can load it with symbols you’ve generated locally. If you don’t have the source or PDB for a third-party driver, you can still disassemble the offset and reason about what the code was doing.

The Hard Truth About Reading Dumps

This work is tedious. It requires patience, familiarity with operating system internals, and a willingness to accept that some crashes won’t yield clean answers. Memory is ephemeral. State is complex. The dump you have is a single moment frozen in time, and the root cause might have been set in motion seconds or minutes before the actual crash.

But when you’re staring at a production outage that affects thousands of users, and the logs show nothing useful, and the monitoring dashboards just confirm that something died—opening that dump file and tracing the fault to a specific driver, a specific function, a specific line of logic—that’s not just debugging. That’s forensic engineering. And it’s a skill that will never be obsolete.

FAQ

Can I analyze a memory dump without symbols?

Yes, but it’s significantly harder. Without symbols, function names won’t resolve, and you’ll see raw addresses or module+offset notation instead. You can still disassemble the code at the crash address, inspect registers, and examine memory. The bug check code and parameters remain readable. However, you’ll need to rely more heavily on assembly analysis and pattern recognition. Always attempt to obtain symbols—public symbol servers cover all Microsoft binaries, and you should keep PDBs for your own builds.

What’s the difference between a minidump and a full dump?

A minidump contains only essential data: the bug check code, processor context for the crashing thread, stack memory, and a list of loaded modules. A full dump contains the entire contents of physical memory at the time of the crash. Minidumps are small (typically under 1MB) and cover most common debugging scenarios. Full dumps can be tens of gigabytes on modern systems but are necessary when you need to inspect user-mode memory, examine processes other than the crashing one, or investigate memory corruption that spans large regions.

How do I know if a crash was caused by hardware or software?

Start with the bug check code. 0x00000124 (WHEA_UNCORRECTABLE_ERROR) strongly suggests hardware—specifically, a machine check exception reported by the CPU. 0x0000009C (MACHINE_CHECK_EXCEPTION) is similar. Consistent crashes at the same address or in the same driver point toward software. Random addresses, varying error codes, and crashes in different modules each time suggest memory corruption from a bad DIMM, overheating, or power delivery issues. Run !mca in WinDbg to inspect machine check architecture data. Run MemTest86 overnight. Don’t assume software until you’ve ruled out hardware.
OpenTofu 1.9 and the Great Infrastructure-as-Code Realignment

The Fork That Actually Mattered

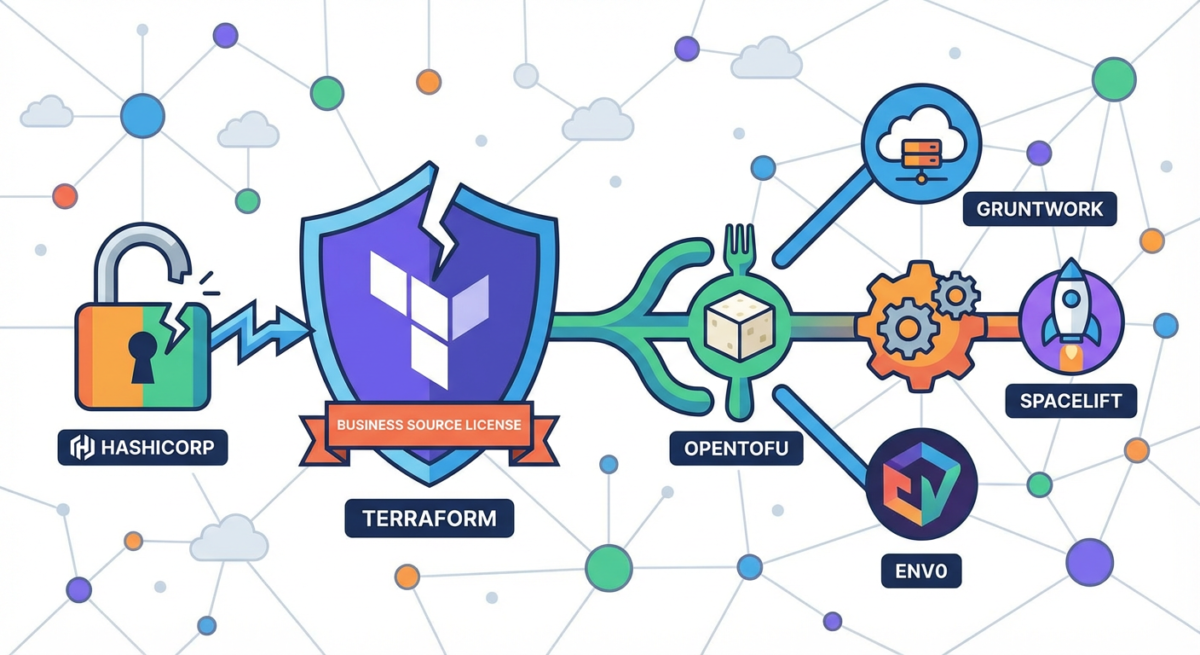
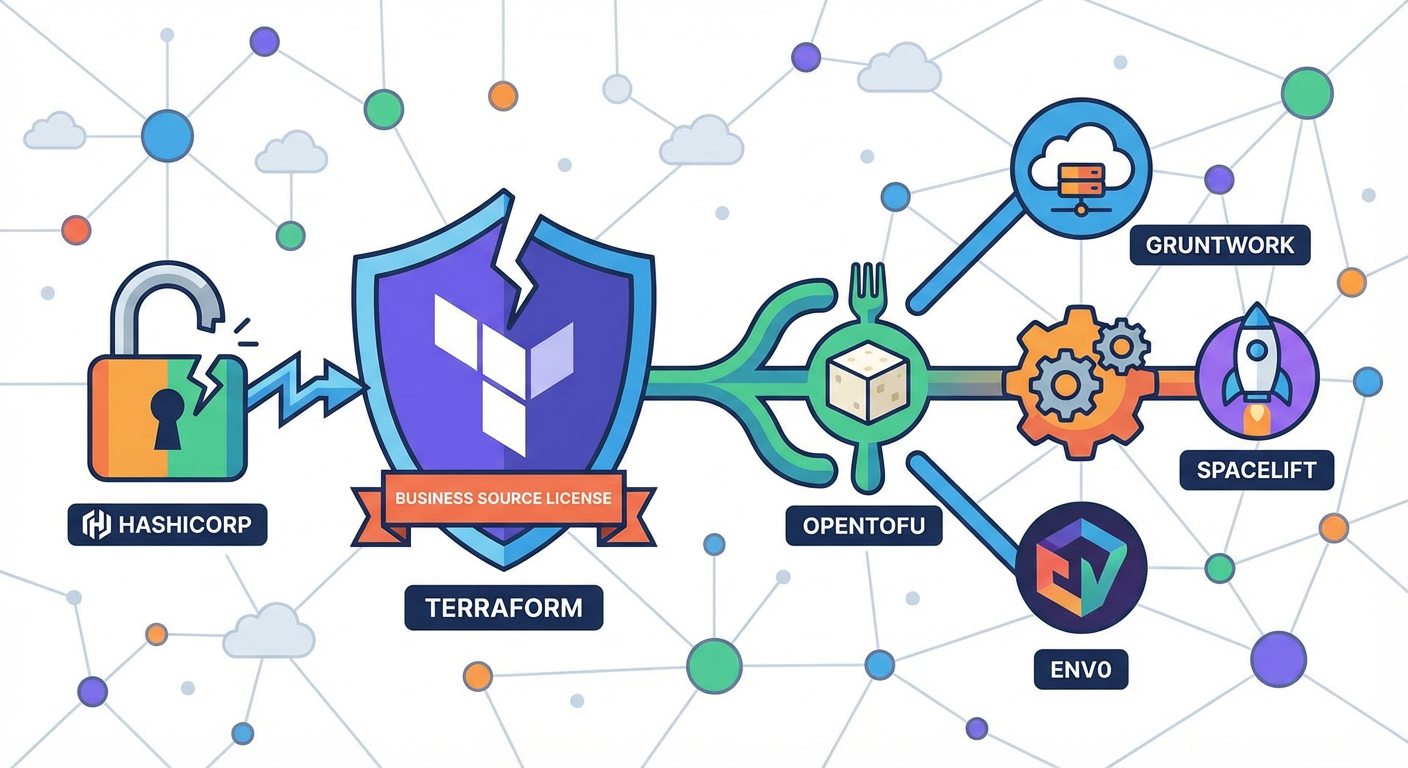
When HashiCorp moved Terraform to the Business Source License in August 2023, most of the industry watched with the detached curiosity of someone observing a distant corporate squabble. Then the Linux Foundation got involved. Then Gruntwork, Spacelift, and Env0—three companies with real skin in the game—started backing a fork called OpenTofu. That’s when you knew something had shifted in the infrastructure-as-code ecosystem.

OpenTofu 1.9 and the Great Infrastructure-as-Code Realignment

What makes this different from the dozen other open-source fragmentation events we’ve seen is the specificity of the grievance and the quality of the response. This wasn’t ideological posturing. Major infrastructure companies were saying: we cannot build products on top of a tool whose licensing terms might change overnight. They had something to protect, and they had the engineering talent to act on it. By late 2024, OpenTofu hit version 1.9 with features—provider-defined functions and early variable evaluation—that Terraform hadn’t shipped yet, even as Terraform sat constrained under BSL restrictions.

Understanding the Licensing Trap

The Business Source License isn’t quite open-source, and it isn’t quite proprietary. It lives in the legal equivalent of an uncanny valley. The terms restrict commercial use of Terraform for a period of time, meaning companies selling infrastructure services could no longer freely modify and deploy the tool. For a consulting firm or a managed service provider, this was paralyzing. You can’t ship code to clients when the license says you can’t.

HashiCorp’s reasoning was straightforward from a commercial perspective: open-source contributors were building billion-dollar companies on top of their work without paying anything. That’s not a bug in the open-source model; it’s the entire feature. But it was also unsustainable for HashiCorp shareholders. When a company reaches a certain scale and IPOs (or in this case, gets acquired), the pressure to monetize everything becomes relentless.

The fork forced the issue into the light. Restrict the license, and companies will fork. If they fork successfully, you’ve just created your own competition. Not a new lesson in open-source history, but HashiCorp learned it at expensive scale.

IBM’s November Acquisition and the Question Mark

Then IBM acquired HashiCorp in November 2024 for 6.4 billion dollars. Nobody quite saw that coming. IBM doesn’t have a track record of aggressive open-source monetization. Their entire cloud strategy depends on being seen as partner-friendly, as the company that understands enterprise complexity rather than the one squeezing margin from every angle. That creates an interesting dynamic.

The acquisition immediately raised a question in the community: will IBM reconsider the licensing stance? There’s no public signal either way, which is perhaps its own signal. What we do know is that IBM now owns a tool whose fork is outpacing it in feature velocity and whose user base is increasingly nervous about long-term direction. That’s not a comfortable position, even for a company with IBM’s resources. The market has spoken, and it said it prefers to trust a Linux Foundation-backed fork over a BSL-restricted tool owned by any single commercial entity, no matter how large.

The Adoption Numbers Tell a Story

Here’s where the data becomes almost comical in its clarity. According to the CNCF 2024 Cloud Native Survey results, Terraform remained the most widely used infrastructure provisioning tool at 60% adoption across the cloud-native community. That’s remarkable stability for a tool under this much uncertainty. But OpenTofu had already captured 17% adoption in less than a year post-fork. Think about that velocity. A fork of a mature project usually gets abandoned within months. OpenTofu is gaining real traction.

Meanwhile, Pulumi—the alternative infrastructure-as-code platform that lets you write infrastructure in general-purpose languages instead of HashiCorp Configuration Language—reported 200% year-over-year growth in enterprise customers through 2024. Pulumi directly benefited from the licensing chaos. Every company that said “maybe we should diversify away from Terraform” looked at Pulumi, and many of them stayed. That’s the hidden tax of the BSL experiment: not just fork adoption, but market share migration to completely different categories of tooling.

For organizations with thousands of lines of Terraform code, switching to Pulumi is genuinely painful. You’re not just changing tooling; you’re rewriting. Yet enough people have decided that pain is worth the security of knowing their infrastructure platform won’t be yanked into some restrictive licensing model.

What This Means for Your Decisions Right Now

If you’re starting a new infrastructure project, the honest answer is that both Terraform and OpenTofu are viable. But the question you should ask yourself is about risk tolerance. With Terraform, you’re betting that IBM’s ownership will result in a more permissive licensing posture eventually, or you’re accepting the BSL restrictions as a permanent part of the architecture. With OpenTofu, you’re betting on Linux Foundation governance, which has its own limitations but at least has a track record of not springing surprise licensing changes on you.

For teams already deep in Terraform, you’re not in immediate danger. Your existing code runs fine. The real pressure point comes when you need to build commercial products on top of your infrastructure code or when you’re making architectural decisions about tooling five years out. That’s when the licensing question becomes concrete.

The most interesting move right now is IBM’s next step. If they signal that Terraform will return to truly open-source licensing, even a weak signal, the fork war probably ends quickly. OpenTofu demonstrated that the community could execute, and that was enough to create leverage. But if IBM maintains the BSL status quo, we’re probably looking at a permanent split in the ecosystem. Not because OpenTofu is dramatically better—though 1.9’s feature set is respectable—but because community trust, once broken, takes years to rebuild.

For the latest developments in this space, check the OpenTofu official project and changelog and keep an eye on HashiCorp’s public statements under new ownership. The infrastructure-as-code ecosystem is at an inflection point, and watching how these companies navigate it will tell you a lot about where enterprise tooling is headed. What’s your take on how this should resolve?

Claude 3.7 Sonnet’s Extended Thinking Mode: The Production Reality Behind the Benchmark Wins

The February 2025 Release: What Actually Changed

Anthropic shipped Claude 3.7 Sonnet in February 2025, and the headline everyone grabbed was the extended thinking mode. If you’ve been in this space long enough, you’ve learned to be skeptical of mode announcements. They usually sound more impressive in the press release than they feel in the actual code. This one is different, though not in the way you might expect.

Extended thinking lets the model do multi-step reasoning before committing to output, and here’s the key detail that matters: you can configure token budgets up to 128K tokens for that reasoning process. This isn’t a binary feature flip. It’s a knob you turn, which means you’re making real architectural choices about how much “thinking time” your pipeline gets to spend on each request. That’s the engineer’s problem, and it’s exactly the kind of problem worth understanding before you deploy this to production.

Also worth noting is how fast the cloud side moved. AWS Bedrock had Claude 3.7 Sonnet available within weeks of launch. That’s fast enough to signal genuine enterprise demand, and it matters for anyone already living inside the AWS ecosystem. One less integration conversation with your platform team.

The Benchmark That Actually Matters for Your Job

Look at the SWE-bench Verified leaderboard and you’ll see Claude 3.7 Sonnet scored 70.3% on autonomous coding tasks at release, putting it ahead of GPT-4o and Gemini 2.0 Pro. That’s not a small thing. Autonomous coding evaluations measure whether a model can take a GitHub issue, write actual code, run tests, and iterate without human intervention. It’s close to what production pipelines actually need.

Here’s why this matters to your career specifically: this is the benchmark that correlates with real engineering work. Not token prediction accuracy on some synthetic dataset. It’s “can this system fix the bug or not.” When you’re evaluating models for internal tooling, code generation APIs, or autonomous agents, SWE-bench performance is the one you reference in meetings. It shifts the conversation from theoretical capability to applied capability, which is where your credibility comes from as a senior engineer.

That said, benchmarks are benchmarks. They’re the floor, not the ceiling. You still need to run your own evals against your actual use cases, your codebase patterns, your error types. But having a model that performs this well on the public benchmark gives you something concrete to anchor your internal testing against.

The Latency Tax You Need to Budget For

Here’s where the pragmatism kicks in. Extended thinking mode adds 15 to 40 seconds of latency per complex query, depending on how many tokens you budget for the reasoning phase. That’s the real cost structure, and you can’t wish it away with optimization.

For batch jobs, scheduled analysis, or internal tooling, that’s acceptable overhead. You run it overnight, you get better results, everyone wins. For user-facing endpoints, customer-facing APIs, or anything with a sub-second SLA, extended thinking becomes a tactical decision rather than a default. You enable it selectively. Maybe on the retry path when standard mode gives you a low-confidence answer. Maybe on weekend processing when traffic is lighter. Maybe not at all.

This is exactly the kind of decision that separates production-hardened architectures from demo implementations. Know your latency requirements first, then evaluate whether extended thinking fits your budget. Not the other way around.

The Cost Story That Actually Determines Adoption

Developers on the Anthropic forum reported 2 to 3x higher costs per task when extended thinking is enabled versus standard mode. This brought back the cost-versus-capability debate with real numbers attached. That’s the conversation that happens in expense review meetings, and frankly, it matters more than benchmark scores when you’re pitching this to finance.

The math is straightforward: extended thinking consumes more tokens during the reasoning phase, and those tokens cost money. You’re paying for transparency into the model’s reasoning process, which is genuinely valuable for debugging, auditing, and understanding failure modes. But it’s not free, and pretending it doesn’t factor into your decision-making is how you end up with a 10x budget overrun halfway through the quarter.

If you’re building something where accuracy drives revenue directly (trading systems, medical diagnostics, fraud detection), the 2 to 3x cost multiplier might be worth it. If marginal quality improvements don’t move the needle in your use case, it’s harder to justify. Run the economics. Use actual customer impact estimates. Make the decision intentionally.

How This Shapes Your Next Deployment Decision

Claude 3.7 Sonnet with extended thinking is good enough to be a serious consideration for autonomous agents, code generation pipelines, and complex reasoning tasks. It’s not universally better than everything else for everything. That’s not how production systems work. You’re making trade-offs on latency, cost, capability, and integration complexity every single time you pick a model.

Extended thinking mode represents a philosophical shift toward paying for reasoning as a first-class resource rather than hoping the model figures things out in one pass. It’s explicit, configurable, and measurable. Those are engineer-friendly properties. Check the Anthropic Claude 3.7 Sonnet release announcement for the exact API details, then run a pilot on your actual workloads with the token budget dialed in for your latency requirements.

The best models are the ones that fit your constraints, not the ones that win the most benchmarks. If extended thinking fits your pipeline, the numbers justify it, and your customers benefit from the quality improvement, deploy it. If not, standard mode is still extremely capable. Either way, you’re making an informed decision based on production reality rather than hype.

What’s your actual experience been with extended reasoning modes in production? Hit me up if you’ve got specific use cases that either worked or fell apart. There’s always more to learn from what actually ships.

Rust in the Linux Kernel at Scale: Two Years of Merge Commits Later, What the Kernel Mailing List Drama Actually Tells Us

The Scale Shift Nobody Expected (Except Everyone Who Was Paying Attention)

When Rust support officially merged into the Linux kernel in late 2022 with version 6.1, the tree contained roughly 13,000 lines of Rust code. I remember the mood on the kernel mailing list felt like cautious optimism mixed with academic curiosity. “Fine, let’s try this,” seemed to be the consensus. “But it better not break anything.” Fast forward to early 2026, and we are looking at over 600,000 lines of Rust across drivers, filesystem abstractions, and core subsystem bindings. That is not a gradual adoption curve. That is a phase transition.

What strikes me most about this trajectory is what it represents operationally. You do not go from 13,000 to 600,000 lines of code in a production-critical system without something fundamental shifting in how maintainers and contributors view the tradeoff between safety guarantees and implementation friction. The cynical interpretation is that Rust advocates finally won the political battle. The honest interpretation is messier and more interesting: the kernel community collectively realized that memory safety bugs were eating their lunch, and Rust was the least terrible solution available.

When Your GPU Driver Lives in Rust

The watershed moment came with NVIDIA’s Nova GPU driver initiative. Linus Torvalds confirmed in a December 2025 kernel mailing list post that Rust driver contributions have accelerated significantly, with Nova representing the highest-profile all-Rust driver effort to date. Let me be direct: getting a GPU driver merged into the mainline kernel is already a production-readiness marathon under the best circumstances. Getting one written entirely in Rust past skeptical reviewers required technical excellence that could not be hand-waved away.

What Nova proved was not just that you could write complex device drivers in Rust. It proved that the abstractions the kernel community had developed over three years were solid enough to handle something genuinely hard. I spent a weekend reading through the Nova submission threads, and the technical feedback was real. People were not rubber-stamping it because it was Rust. They were engaging with the actual design decisions. That is how you know a technology has stopped being a religious argument and started being a tool.

The Numbers Started Talking, and They Were Loud

Here is where the conversation shifted from philosophy to pragmatism. A 2025 study from the University of Waterloo analyzing 150 kernel CVEs from 2020-2024 found that 67 percent fell into memory safety categories that Rust’s ownership model structurally prevents. Seventy years of C, and it turns out that a significant majority of security vulnerabilities in the kernel trace back to problems that Rust simply does not allow you to create in the first place. You cannot have a use-after-free bug in Rust code. You cannot have a buffer overflow through naive indexing. The language does not let you.

This is not theoretical. This is not “Rust is safer if you follow best practices.” This is structural. The compiler refuses. For kernel developers accustomed to defensive programming as a way of life, that shift registers differently when you see it backed by empirical analysis of real CVEs.

Google’s Android team reported in a 2025 blog post that the proportion of new Android OS code written in memory-safe languages reached 77 percent, with Rust accounting for the majority of systems-level additions. More importantly, memory safety vulnerabilities in Android dropped to below 24 percent of total CVEs for the first time. You can argue about correlation and causation all you like, but when a platform that ships on billions of devices shows that metric, people listen. Check their Google Security Blog on memory safety in Android for the full breakdown. The data is public.

The Abstractions Tax Started Coming Due

Now here is where I have to put on my honest face and acknowledge that nothing in systems programming is free. In late 2025, veteran C maintainer Ted Ts’o posted a detailed technical critique arguing that Rust’s abstraction layers were creating hidden performance regressions in I/O paths that benchmarks were not capturing. And he was not wrong. He was not being a Luddite. He was being precise.

The argument goes like this: Rust’s abstractions force certain patterns. Those patterns are safe, yes. But safe is not free. Compiler optimizations have to work harder. The abstraction boundaries do not always align perfectly with hardware realities. When you are talking about code paths that execute billions of times per second across millions of servers, a small hidden cost becomes audible.

This critique mattered because it shifted the conversation away from “Rust versus C as an ideology” into “where do these abstraction costs actually manifest, and are they worth the safety gains?” That is a conversation you can have empirically, where you can measure things. The kernel mailing list threads that followed were dense, technical, and remarkably civil by historical standards. People were arguing about specific performance profiles, not about whether Rust belonged in the kernel. That is progress.

What This Actually Tells Us

Looking back from 2026 at the landscape that has emerged over two years of merge cycles, a few things become clear. First, the Rust transition in the kernel is real and accelerating, but it is not displacing C wholesale. It is expanding into new problem domains where the safety guarantees justify the abstraction costs. That is the sustainable path.

Second, the technical community has genuinely grappled with the tradeoffs instead of retreating into tribal signaling. Yes, there was drama on the mailing list. Kernel development drama is not new. But the drama has been the friction of genuinely difficult engineering questions, not ideology. When I read threads about Rust abstractions and I/O performance, I am reading the same careful reasoning I would see in threads about CPU cache behavior or network stack optimization. That normalization is the most important signal.

Third, and perhaps most importantly: when you have empirical data showing that 67 percent of kernel CVEs trace to problems Rust structurally prevents, and you have a platform like Android showing real-world security improvements, you have crossed a threshold where the burden of proof flips. The question is no longer “why Rust?” It becomes “why not Rust, in this particular context?” That shift is irreversible.

For anyone still following this evolution, the practical takeaway is to stop viewing Rust in the kernel as a binary choice. Check out the Linux kernel Rust documentation and understand where it is actually deployed and why. The drama you see on the mailing list is not a sign of failure. It is a sign of a community taking difficult engineering seriously.

What has your experience been with Rust in production systems? Have you hit those abstraction costs Ted Ts’o identified, or do your workloads sit in the “safety wins” category? The conversation is far from over, and I am genuinely curious what practitioners are seeing on the ground.

OpenTelemetry Is Now Table Stakes: How the OTel 1.0 Stable Spec Is Reshaping Observability Vendor Lock-in in 2026

The Stability Inflection Point Nobody Really Saw Coming

In 2024, something genuinely quiet but consequential happened in the observability world. OpenTelemetry’s specification for logs, metrics, and traces all hit 1.0 stability simultaneously. Not beta. Not “mostly ready.” Actual, ship-it-to-production-with-confidence stable. For those of us who remember the pre-OTel era of lock-in nightmares and rip-and-replace migrations, this was the moment when the architectural foundation finally solidified under our feet.

By early 2026, the momentum shifted from niche adoption to mainstream inevitability. The CNCF project metrics tell the story more clearly than any analyst report ever could: OpenTelemetry became the second most active project in their entire portfolio by contributor count. Only Kubernetes outpaced it. That’s not hype. That’s an entire ecosystem deciding, collectively and voluntarily, that this is the floor for how observability gets instrumented going forward.

What made this different from other “standardization” efforts that promised the world and delivered PowerPoint? The specification matured without becoming a bureaucratic nightmare. The API stayed clean. The wire protocols actually worked across vendors. Most critically, the tools started shipping real implementations instead of treating OTel as something they’d “eventually support.”

How Vendors Got Forced to Compete on Merit Instead of Lock-in

Here’s where it gets genuinely interesting from a market dynamics perspective. Datadog, one of the most observability-forward companies on the planet, hit their earnings call in Q3 2025 with a number that should have made every observability engineer sit up straight: 34 percent of their new enterprise customers arrived already instrumented with OpenTelemetry. Not asking about it. Not evaluating it. Already shipping it. Their CEO, Olivier Pomel, explicitly acknowledged that this fundamentally changed how they approached customer onboarding and pricing conversations.

Think about what that actually means. For years, the classic sales motion was: “Use our agent, our SDK, our magic pixie dust. You’re now invested.” Now you walk in the door having already made the portability investment upfront. The vendor gets evaluated on what they do with your data after it arrives, not on whether they’ll hold it hostage behind proprietary instrumentation.

That’s not a minor shift. That’s the whole economic model getting inverted. Honeycomb’s 2025 State of Observability report surveyed a thousand engineers and found that 58 percent of them cited vendor portability as their primary motivation for adopting OpenTelemetry. Not cost reduction, though that came in at 44 percent. Not performance. Portability. The ability to walk away with your telemetry intact.

What’s fascinating is how fast the major cloud providers responded to this reality. AWS, Google Cloud, and Azure all announced native OpenTelemetry pipeline support in their managed observability services throughout 2025. That’s the equivalent of every major gas station deciding they’ll pump Shell, Chevron, or Exxon fuel into the same cars. You’re not locked into the station anymore. You’re just locked into needing gas.

Getting Started Without the Paralysis

If you’re reading this thinking “okay, but where do I actually begin,” let me cut through the analysis paralysis. The beauty of OpenTelemetry hitting stability in 2024 and gaining this critical mass adoption by 2026 is that the beginner path is finally, actually, straightforward.

Start with the OpenTelemetry project documentation. Not because it’s revolutionary prose, but because the documentation now assumes you’re someone who wants to actually ship something next week, not someone reading a spec for the first time. Pick your language. Pick one signal. Traces are usually the least intimidating starting point. Get your first service instrumented. Ship it.

The Collector piece is where the real leverage lives. By late 2025, the OpenTelemetry Collector was processing over 10 billion daily spans across known public deployments. That’s a four times increase from 2023. Not because it’s trendy. Because it genuinely works as the central nervous system for telemetry routing. You instrument your code once with OTel. The Collector handles the complexity of where it goes. Want to ship to multiple backends simultaneously for redundancy or cost optimization? The Collector handles it. Want to sample dynamically based on error rates? The Collector handles it.

The practical implication: you’re no longer making a binary choice between vendors. You’re making a choice about where your Collector instances live and what you do with the data once it’s there.

The Collector as Your Sanity Preservation Layer

One of the best architectural decisions you can make right now is treating the OpenTelemetry Collector as a critical infrastructure component, not an optional optimization. This isn’t about collecting badges for your resume. This is about buying yourself future flexibility that 3-AM-you will genuinely appreciate.

If you’ve been in this industry long enough, you’ve experienced at least one observability vendor surprise. A pricing model change. A feature sunset. A performance regression. Sometimes all three in the same quarter. Every one of those moments becomes significantly less destructive if your instrumentation is already decoupled from any single vendor’s pipeline.

The architectural pattern is simple: your code ships OTel signals to a local Collector instance. The Collector batches, samples, and routes. Your backend gets clean, efficient data in whatever format it natively understands. If you need to swap backends, you reconfigure the Collector. Your code? Unchanged. That’s not a small amount of insurance.

Check out the CNCF project metrics and devstats to see which exporters and receivers are getting the most attention. Active development is a decent proxy for “this won’t be unmaintained in six months.” The Collector ecosystem is reaching the point where you can likely find a working exporter for any backend you care about.

What This Actually Means for Your Next Architecture Decision

If you’re starting a new observability initiative in 2026, choosing proprietary instrumentation as your starting point is a legacy decision. Not because proprietary agents are inherently bad. They’re often incredibly well-engineered. But you’re paying for lock-in you don’t need anymore and getting less flexibility than the open standard offers.

The inflection has happened. The ecosystem has the velocity. The documentation has matured. The vendor support is real. The cloud providers are shipping native support. The market has clearly moved. This isn’t about evangelism or ideology anymore. It’s just pragmatism.

Start small. One service. One signal. Get comfortable with how OTel actually works on your infrastructure instead of how it works in theory. The Collector handles the complexity of connecting multiple backends, so you don’t need to solve everything on day one. You can iterate toward your ideal architecture without rip-and-replace migrations.

What observability decisions are you wrestling with right now? Have you encountered situations where vendor lock-in created friction, or are you just starting to think about how OpenTelemetry fits into your infrastructure? Drop a note in the comments or grab me on whatever platform you hang out in. The most interesting observability problems rarely have clean answers, and I’m genuinely curious what’s on your team’s radar.

The Real Cost of AWS Graviton4 vs. Azure Cobalt 100: A Workload-by-Workload Breakdown for 2026

The Arm Transition Is No Longer Theoretical

We’ve reached an inflection point. By late 2025, Arm-based instances accounted for roughly one in five new EC2 launches on AWS. That’s not early adopter territory anymore. That’s momentum. Azure Cobalt 100 hit general availability across most regions in mid-2025, and Google Cloud’s Axion processor arrived around the same time. The major cloud providers are no longer hedging on custom Arm architectures. They’re all-in, and they’re pricing accordingly.

What makes 2026 different from the perpetual “Arm is coming” conversation of previous years is specificity. We now have production data. We have real workloads running for months on these chips. We have customers making actual cost decisions instead of theoretical ones. That’s the signal worth paying attention to.

Graviton4’s Play: Memory-Intensive Workloads and the Price-Performance Gap

AWS released Graviton4-based R8g instances in late 2024, and the headline numbers caught everyone’s attention: up to 30% better price-performance than the Graviton3 generation for memory-intensive workloads. That’s meaningful improvement velocity. The R8g instances scale up to 768 GB of memory, and AWS priced them aggressively, roughly 15 to 20% cheaper per GB compared to equivalent x86 r6i instances for many configurations.

More interesting than the marketing claims is what third-party benchmarking revealed. A Principled Technologies study from 2025 showed Graviton4 delivered 40% higher throughput per dollar on Java-based microservices compared to comparable x86 Intel Xeon instances. For Java shops, and there are still plenty of them in enterprise, that’s a compelling needle-mover. The architecture handles JVM warmup efficiently, and the memory bandwidth characteristics suit heap-heavy applications.

Where Graviton4 pulls away is databases and in-memory caches. Redis workloads see particularly strong gains. DynamoDB users running provisioned capacity suddenly find themselves doing more work for less cost. If your application is cache-heavy or database-heavy, AWS Graviton4 Instance Types deserve a serious evaluation.

The constraint? Single-threaded performance remains the Achilles heel for compute-bound tasks. For workloads that can’t be parallelized effectively, you’re trading some per-core performance for per-dollar economics. That’s a deal that works if your architecture supports it and painful if it doesn’t.

Cobalt 100’s Approach: Broad Versatility and Enterprise Hedging

Microsoft took a different philosophical approach with Azure Cobalt 100. Rather than optimize for a specific workload category, they aimed for a broader sweet spot. The processor tops out at 128 vCPUs per VM, uses the Ampere Altra architecture as its foundation, and reached general availability across Azure regions in mid-2025. Microsoft’s framing is deliberate: this is an Arm chip that runs anything x86 does, just cheaper.

Cobalt 100 doesn’t have a flashy headline like “40% better throughput.” Instead, it promises consistency. General-purpose workloads see roughly 15 to 25% cost savings compared to equivalent D-series x86 instances. That’s solid but less dramatic than Graviton4’s specialized wins. The philosophy here is risk mitigation for enterprises: real cost savings without betting your application stack on architecture-specific optimizations.

The practical advantage for many organizations is organizational simplicity. You don’t need to profile your workload extensively to know if Cobalt will work. Spin up a test instance, run your application, measure performance. If it’s within 5 to 10% of your x86 baseline, the cost savings kick in immediately. Azure Cobalt 100 Overview emphasizes this broad compatibility story.

Where Cobalt struggles slightly is the specialized workload narrative. If you’re running Java microservices at massive scale, Graviton4 probably edges it out. If you’re doing heavy machine learning inference, Google Cloud’s Axion, which claims 50% better performance per watt than comparable x86 N2 instances, might pull ahead on efficiency metrics. Cobalt is the generalist in a field of specialists.

Workload-by-Workload Reality: Where Each Chip Wins

Container orchestration and Kubernetes clusters favor Graviton4, especially if you’re budget-conscious on the infrastructure layer. The memory efficiency and relatively strong multi-threaded performance make large Kubernetes node pools economical. I’ve seen organizations cut their EKS infrastructure costs by 20 to 30% by migrating existing deployments to R8g instances with minimal application changes. That’s not hype; that’s the spreadsheet math.

Web servers and traditional application stacks work equally well on both. If you’re running Django, Rails, or Node.js applications, you’ll see comparable cost savings across Graviton4, Cobalt 100, and Axion. The performance differences are negligible. Choose based on cloud commitment and team familiarity. This is where most enterprises land, boring reliability with a cost advantage.

Database workloads deserve granular analysis. Time-series databases like InfluxDB or Prometheus love Graviton4’s memory bandwidth. Relational databases like PostgreSQL perform well across all three, though Graviton4’s pricing on high-memory configurations (R8g) edges out the competition. If you’re running a data warehouse or doing heavy analytics, Axion’s power efficiency becomes relevant for TCO calculations when you factor in cooling costs.

Batch processing and scientific computing are where Cobalt shows its versatility. It’s not the fastest, but it’s predictably fast and predictably inexpensive. For Monte Carlo simulations, financial modeling, or large-scale data processing that doesn’t require GPU acceleration, Cobalt’s broad compatibility means you’re not rewriting code to chase marginal efficiency gains.

The Pricing Paradox and Your 2026 Strategy

Here’s the uncomfortable truth: as adoption increases, pricing pressure will compress the cost advantages. AWS and Azure are both playing volume games now. Graviton4’s 30% advantage over Graviton3 is real, but expect that lead to stabilize as volume ramps. The same applies to Cobalt. By 2026, we’ll likely see 10 to 15% sustainable cost advantages rather than the aggressive early-adopter discounts we’re seeing now.

That means your decision framework should shift from “which is cheapest” to “which is cheapest for my workload category and where is my team comfortable.” If you’re AWS-native and running memory-intensive applications, Graviton4 is almost certainly the right call. If you’re a multi-cloud shop or running general workloads, Cobalt offers lower organizational risk. If you’re optimizing for power efficiency and have time to profile carefully, Axion deserves evaluation.

The bigger strategic question is simpler than it seems: can your development team maintain Arm-based infrastructure competently? Not all of them can yet. Not all container images have Arm builds available. Some legacy dependencies still don’t compile cleanly on Arm64. These operational realities matter more than per-CPU performance differences. The cheapest processor is the one your team can actually operate without midnight incidents.

I’m genuinely interested in where this is going. Custom Arm processors in cloud are no longer interesting because they’re novel. They’re interesting because they work and they’re economical at scale. The noise is clearing. What patterns are you seeing in your infrastructure costs? Where are you planning to pilot these chips in 2026? I’d genuinely like to hear what’s working and what isn’t in your environments.

Why GitHub Copilot Workspace’s Agentic Mode Is Both Impressive and a Liability You Haven’t Planned For

The Capability That Actually Delivers (And Why That’s Complicated)

Let me start with what matters: GitHub Copilot Workspace’s agentic mode genuinely works. This isn’t hyperbole born from hype cycle intoxication. The numbers are real. Over 77,000 organizations have adopted Copilot Workspace as of late 2025, and those deployments are completing an average of 3.2 multi-file edits per session. Translation: the thing is orchestrating meaningful changes across codebases without a human hand-holding it through every keystroke. That’s not autocomplete theater anymore. That’s actual agent behavior.

The efficiency gains are the kind of thing that make your engineering director sit up straighter in budget meetings. Boilerplate coding time dropped by 41 percent in the teams Microsoft telemetered during their GitHub Universe 2025 presentation. Think about what that means on your team’s runway. If your squad spends two weeks a quarter grinding through database schema scaffolding, form validation patterns, and API endpoint stubs, you just bought yourself a week back. For junior engineers, it’s frankly transformative as a learning accelerant and a friction reducer.

But here’s the thing nobody’s talking about with enough urgency: that 41 percent productivity gain came with a 28 percent increase in code review queue depth on the same teams. The agent is generating code faster than your review process can absorb it. That’s not a feature gap. That’s a systemic problem wearing a productivity bow.

The Security and Governance Blindside

I’ll cut to the uncomfortable part: your organization probably doesn’t have governance scaffolding for this yet. Most don’t. Gartner’s 2025 Hype Cycle report placed AI-augmented software development squarely at the Peak of Inflated Expectations, and they weren’t gentle about calling out the governance gaps lurking underneath those expectations. Enterprises are deploying autonomous coding agents into production pipelines with controls that would look quaint if applied to database access or infrastructure provisioning. But for code generation? We’re apparently winging it.

The security picture got darker in Q4 2025 when GitHub published advisories around a new class of prompt injection vulnerabilities specific to agentic coding environments. We’re talking CVE-2025-series disclosures here. These aren’t theoretical. An attacker who can inject instructions into your agent’s context, through a malicious dependency, a comment in a GitHub issue, or a pull request description, can potentially manipulate the agent into generating code that does things you absolutely did not intend. The agent has no values alignment. It has optimization targets. Feed it the right prompt sequence and it will optimize toward your worst day.

A Stack Overflow Developer Survey from 2025 found that 62 percent of developers using AI coding agents reported at least one instance of unreviewed code reaching a staging environment. Read that again. Nearly two-thirds. That’s not an edge case. That’s a pattern. That’s a signal that the friction between agent velocity and human oversight has crossed a threshold where human oversight is losing.

Where Your Review Process Collapses

Let’s talk about what happens on your team specifically. Your senior engineer is deep in a feature branch. The agentic mode spins up and commits six files across two services. The changes look reasonable on surface scan. Your CI tests pass. Maybe you spot a variable naming inconsistency or a missing edge case comment. You approve it. Three weeks later, during an incident, you realize the agent made an assumption about failure mode handling that was never articulated anywhere, and your monitoring blind spot let it slip past review.

The core problem is cognitive load asymmetry. The agent can generate code at whatever velocity your API allows. Human reviewers cannot review at that velocity while maintaining the same rigor they’d apply to human-authored PRs. Something has to give. Usually it’s rigor. We start approving faster. We trust the agent’s test coverage. We assume the agent won’t do something truly stupid. Then the agent does something truly stupid in a way we didn’t predict, and you get to debug that at scale.

This is where the productivity number inverts on you. You saved time generating code. You then spent more time in review queues, context-switching, or worse, incident response. The 41 percent win evaporates into a 28 percent deeper review backlog, plus whatever your actual incidents cost.

What You Actually Need to Do Right Now

First, stop treating agentic mode as a feature flag you flip and walk away from. You need governance before you scale it. That means human review thresholds that match agent confidence scores, scope limitations on what domains the agent can touch without explicit approval, and audit trails that let you reconstruct why the agent made any given decision. You need GitHub Copilot Workspace documentation and agent capabilities reviewed not just by your security team but by your principal engineer who understands your system’s failure modes.

Second, invest in review infrastructure that scales with agent velocity. This might mean automated verification gates that check for anti-patterns the agent tends toward, or asynchronous review workflows where senior engineers spot-check agent changes rather than deep-diving every one. It definitely means not pretending your current review process works when agent throughput is 5x what it was last year.

Third, be honest with your team about what this technology is actually optimizing for. It’s not optimizing for code quality or architectural coherence. It’s optimizing for token efficiency and pattern matching. Your job is to define the boundaries where those optimizations are safe and where they need friction. That friction is a feature, not a bug.

The Signal in the Noise

None of this means you should avoid agentic mode. The capability is real and the efficiency gains are genuinely valuable in the right context. But you need to approach it the way you’d approach any powerful abstraction: with intentionality about where the abstraction breaks down and what falls out of view when you use it.

We’re at an interesting point in the hype cycle. Gartner Hype Cycle for Emerging Technologies 2025 places this right at peak expectations, which means the correction is coming. Some teams will hit that correction hard. The teams that won’t are the ones building governance and review scaffolding now, while it still feels like overkill. Because it won’t feel like overkill once you’re debugging an agent-generated production incident at 3 AM.

Have you started auditing what your agentic deployments are actually generating? Have you hit a moment where the agent made you uncomfortable? I’d genuinely like to hear what you’re seeing on your end.

Kubernetes 1.32’s Persistent Volume Resize Finally Works. Yes, Really.

The Problem That’s Haunted Every Stateful Deployment

If you’ve run stateful applications on Kubernetes for more than a few months, you’ve encountered the moment. A database pod hits disk limits. You need to expand the persistent volume. You discover that resizing storage on a live pod means choosing between a maintenance window or watching your application degrade. This isn’t a theoretical edge case. It’s a recurring nightmare for anyone managing production databases, message queues, or other data-intensive workloads at scale.

Kubernetes 1.32's Persistent Volume Resize Finally Works. Yes, Really.
Kubernetes 1.32’s Persistent Volume Resize Finally Works. Yes, Really.

The fundamental issue stems from how Kubernetes has historically handled persistent volumes. Expanding storage capacity required destroying and recreating the pod, which meant data migration, potential data loss if done incorrectly, and service interruption. In environments where uptime is measured in nines, this constraint has been quietly burning ops teams for years. You’d resize the underlying volume, but the pod wouldn’t recognize the change. Deleting and restarting the pod meant risking data consistency in stateful systems where that risk isn’t theoretical.

Workarounds emerged, of course. Some teams maintained complicated automation to drain pods gracefully before expansion. Others oversized volumes by significant margins to avoid this scenario entirely, wasting resources and delaying the inevitable. The real solution required fixing Kubernetes itself, not just working around it.

What Kubernetes 1.32 Actually Changed

In December 2024, the Kubernetes project released version 1.32, and buried in the release notes alongside the usual incremental improvements was something genuinely significant: the graduation of in-place pod vertical scaling to stable status. This feature has been in alpha since Kubernetes 1.27, and it finally reaches production readiness. The practical implication is substantial. You can now modify CPU and memory resource limits for running pods without requiring a restart or pod recreation.

The storage story goes deeper, though. The same release promoted Volume Group Snapshots to beta status, enabling consistent snapshots across multiple related persistent volumes simultaneously. For anyone running a distributed database or a stateful application with multiple volumes per pod, this changes everything. You can now snapshot your database’s primary volume, write-ahead log volume, and metadata volume in a single atomic operation, guaranteeing consistency that manual snapshots could never achieve. Check the Kubernetes 1.32 release notes for the full technical breakdown.

What makes this particularly elegant is that it solves two separate problems at once. The vertical scaling capability handles the resource constraint case, while Volume Group Snapshots addresses the data consistency problem that has plagued database administrators running on Kubernetes since the platform’s early days.

The Operational Reality at Enterprise Scale

These features matter more today than they would have five years ago, and the numbers illustrate why. According to the CNCF 2025 Annual Survey results, 96% of organizations are now evaluating or actively running containers in production environments. Of those, 84% use Kubernetes specifically. These are the highest adoption figures the survey has measured since it began tracking this data.

What this means practically is that enterprises are running Kubernetes clusters at sizes that turn operational edge cases into common scenarios. Average enterprise cluster size has grown to 80 nodes, up from 50 nodes in 2023. That growth might sound modest, but it dramatically increases the operational blast radius. When resource constraints affect pods across 80 nodes instead of 20, the probability of hitting storage or memory limits jumps significantly.

At that scale, the old workarounds don’t just waste resources. They become liability vectors. Every manual step in a graceful pod shutdown introduces potential for human error. Every oversized volume represents capital inefficiency that multiplies across hundreds of stateful workloads. Every missed snapshot of a critical database during expansion is a potential data loss incident waiting to happen.

Infrastructure-as-Code Changes the Provisioning Story

The Kubernetes improvements don’t exist in isolation. The broader infrastructure ecosystem has also matured in ways that make these capabilities more accessible. OpenTofu, the open-source Terraform fork now under Linux Foundation stewardship, reached stable 1.0 status in early 2025 and has accumulated over 10 million downloads. This accelerates the entire Infrastructure-as-Code workflow that provisions Kubernetes infrastructure in the first place.

The convergence matters because storage policies can now be versioned, tested, and deployed with the same rigor as application code. You’re no longer manually resizing volumes through kubectl commands or hoping your resize operation completes before the next backup cycle. You declare your volume capacity requirements in code, version control it, and let the infrastructure automation layer handle the mechanics. When Kubernetes 1.32 detects a volume resize request, the system already knows whether it’s intentional, approved, and consistent with your declared infrastructure state.

This isn’t just convenience. It’s the difference between ad-hoc operations and systematic reliability engineering. The difference between hoping a resize succeeded and knowing it succeeded through the same deployment pipeline that validated your database configuration.

Looking Forward From Here

Kubernetes 1.32 is a release that rewards patience and attention. The features aren’t flashy. They don’t make for exciting conference talks. But they solve problems that have been persistent, recurring, and costly for anyone running data-intensive workloads on Kubernetes in production.

The graduation of these features to stable status signals something important about where the platform has arrived. Kubernetes has moved beyond proving that you can run containers at scale. It’s now focused on making stateful workloads manageable, reliable, and operationally sane. That shift is subtle but consequential.

If you’re still managing Kubernetes clusters on earlier versions, planning an upgrade to 1.32 makes sense for any environment running persistent workloads. If you’re already on this release, the Volume Group Snapshots feature in particular deserves investigation for any application with multiple storage backends.

Have you encountered storage expansion scenarios that required painful workarounds? What does the path forward look like in your environment now that these capabilities are stable? The conversation around operational improvements to Kubernetes is genuinely worth having.

Aurora DSQL: The Distributed Database That Actually Doesn’t Make You Want to Scream

The Problem Nobody’s Really Solved Until Now

If you’ve ever tried to build a truly distributed SQL database system, you know the feeling. You start with this elegant vision of data replicated across regions, always available, reads fast everywhere. Then you hit reality around 2 AM on a Tuesday when your consistency model decides to have an existential crisis and you’re staring at conflicting writes across three continents. Amazon just quietly dropped something at re:Invent 2025 that actually addresses this without requiring you to become a distributed systems PhD candidate. Aurora DSQL landed with far less fanfare than the AI announcements, but if you’re an engineer responsible for systems that need to stay up everywhere all the time, this one deserves your attention.

Here’s what makes this genuinely interesting: AWS built Aurora DSQL specifically to handle active-active replication across multiple regions with genuine 99.999% multi-region availability. More importantly, your application doesn’t need topology changes to handle regional failures. Reads keep flowing even when an entire region goes dark. That’s not marketing copy. That’s the kind of thing that saves your weekend.

The Architecture Choice That Actually Matters

The real innovation hiding inside Aurora DSQL isn’t visible at first glance. AWS went with an optimistic concurrency control model built on serializable isolation, which sounds like jargon but translates to something practical: they’ve built the system to avoid lock contention rather than manage it. Their internal testing showed lock contention dropped by up to 80% compared to Aurora PostgreSQL in write-heavy scenarios. For context, that’s the difference between a system that scales smoothly and one that develops bottlenecks like a 1990s highway during rush hour.

Think about what this means for your workload. If you’ve ever cursed at PostgreSQL’s SERIALIZABLE isolation level for being slow, you’re reacting to lock overhead. Aurora DSQL sidesteps that problem by making most transactions optimistic, meaning they assume conflicts won’t happen and validate only at commit time. When conflicts do occur, they’re caught and handled cleanly without the system grinding to a halt. It’s elegant enough that you can almost forgive AWS for burying the explanation three layers deep in technical documentation.

The wire-protocol compatibility with PostgreSQL was clearly a deliberate design decision. Your existing drivers, ORMs, and tooling work without modification. You can take a pg connection string in your application and swap out the endpoint. That’s not revolutionary, but it’s precisely the kind of friction removal that actually matters for adoption. One caveat worth flagging: AWS documented over 40 unsupported PostgreSQL features at general availability. You’ll need to verify your specific workload doesn’t lean on anything in that list.

Getting Started Without Losing Your Mind

The beauty of Aurora DSQL for someone just getting their feet wet is that it’s genuinely boring to set up once you decide to try it. Start by working through the AWS Aurora DSQL official documentation first. Don’t skip the getting started section even if you’re tempted. It’s actually well-written and includes practical connection examples.

Here’s the sensible first project: take a simple web application that currently uses a single-region RDS instance, spin up an Aurora DSQL cluster across two regions, and migrate your schema and a subset of your data. You don’t need to go all-in immediately. The point is to understand how your application behaves with actual regional distribution without the stakes being high. You’ll discover patterns in your queries, understand which features matter for your use case, and get a feel for the operational model before you commit.

The AWS Database Blog on Aurora DSQL architecture provides deeper context on how the system handles consistency and failover, and it’s worth reading after you’ve done some hands-on exploration. Reading about architecture after you’ve struggled with actual configuration decisions lands differently. You’ll notice things that pure documentation skips.

The Elephant in the Room: Benchmarks and Real World

AWS published internal stress test results showing Aurora DSQL handling 1 million transactions per second across three active regions. That’s an impressive number. It’s also a number several independent database engineers have raised their hands about, pointing out that internal labs and production systems have different characteristics. The benchmark assumes specific workload patterns, specific network conditions, and probably a development team that knows exactly what they’re doing.

Don’t let that stop you from testing it with your actual workload though. A system capable of those kinds of numbers means the headroom is real even if your production numbers end up being a fraction of the max. Gartner’s 2025 Cloud DBMS Magic Quadrant listed multi-region active-active SQL as one of the top three infrastructure pain points cited by enterprise architects. Aurora DSQL directly answers that pain. The question isn’t whether it works at scale. The question is whether it works for your specific scale and your specific access patterns.

Why This Actually Matters More Than the Noise Around It

Aurora DSQL got dismissed as a quiet announcement because it doesn’t have the flashiness of generative AI infrastructure or the visible appeal of new instance types. But think about what it actually solves: the infrastructure team that’s been maintaining three separate database replication strategies because they needed coverage across regions, the application team that’s had to manage consistency at the application layer because the database couldn’t handle it reliably, the on-call engineer who gets paged at 3 AM because a region failed and reads needed to be rerouted manually.

What makes this approach different from previous commercial attempts is the pragmatism. AWS built this to work with your existing PostgreSQL skills, your existing tooling, and your existing operational muscle memory. They didn’t ask you to learn a new query language or adopt a novel consistency model that requires a PhD to understand. They took hard problems in distributed systems and made them boring, which is exactly what infrastructure should be.

If you’ve been putting off moving toward global active-active replication because the operational complexity seemed overwhelming, now is a reasonable time to run a serious pilot. Start small, measure carefully, and see if this changes what’s possible for your specific systems. What have you built recently that needed the guarantees Aurora DSQL provides? What would you build differently if truly distributed, always-available SQL was a solved problem?

CVE-2025-XXXXX and the Wake-Up Call Nobody Wanted: Why Supply Chain Security Is Still Broken in 2026

The Numbers Don’t Lie, But They Do Hurt

Every time a major vulnerability drops, there’s this ritualistic dance. Security teams scramble. DevOps folks refresh their Slack channels at suspicious intervals. Someone’s boss asks “are we affected?” in a meeting that could have been an email. Then, roughly 48 hours later if you’re unlucky, someone has already weaponized it. That timeline isn’t hyperbole anymore. The Open Source Security Foundation’s latest review confirmed that high-profile vulnerabilities in npm packages are being actively exploited in under two days. Meanwhile, the volume of critical CVEs in the npm ecosystem jumped 28 percent year-over-year. If you’re the type who likes to sleep at night, that’s a difficult pill to swallow.

CVE-2025-XXXXX and the Wake-Up Call Nobody Wanted: Why Supply Chain Security Is Still Broken in 2026

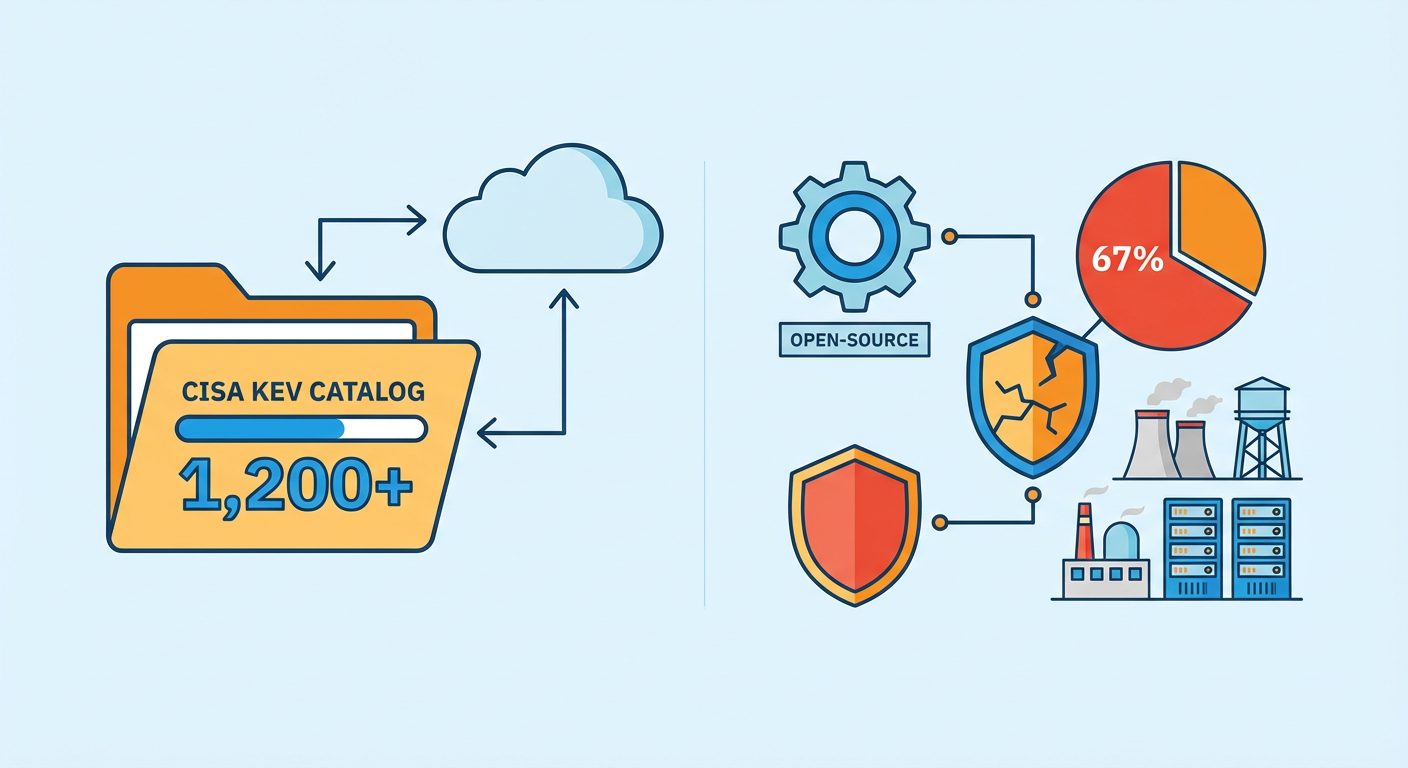
What makes this worse is the sheer scale of exposure. The CISA Known Exploited Vulnerabilities Catalog has crossed 1,200 entries as of end of 2025. That’s not a number. That’s a library of failure. And here’s the part that should genuinely worry your leadership: 67 percent of successful breaches targeting critical infrastructure involved at least one open-source component. Think about that for a moment. Your on-prem systems, your cloud deployments, your microservices architecture, your containerized workloads. All of them are running open-source somewhere in the stack. And statistically, if someone breaches you, they came through that door.

Illustration for CVE-2025-XXXXX and the Wake-Up Call Nobody Wanted: Why Supply Chain Security Is Still Broken in 2026

The Supply Chain Became the Battlefield While We Weren’t Looking

There’s a reason security vendors have pivoted hard toward supply chain defense. It’s elegant from an attacker’s perspective. Why spend resources compromising individual organizations when you can compromise a single widely-used package and watch the blast radius multiply automatically? The math is just too good. According to the Sonatype State of the Software Supply Chain Report, malicious package uploads increased 156 percent compared to 2024. That’s not a gradual trend line. That’s exponential growth in the baseline threat. And the most reliable attack vector remains almost laughably simple: typosquatting. Register a package name that’s one character off from something popular, wait for the tired developer copying from Stack Overflow at 11 PM, and you’ve got foothold.

Socket.dev reported that in a single quarter of 2025, they blocked over 10,000 malicious packages from reaching developer environments. Ten thousand. In three months. From one security vendor. That tells you the volume of trash flowing through the system is staggering. Most of these never make headlines because security teams catch them before the compromised code ever executes. But the ones that slip through? Those become CVE-XXXXX stories. Those become the 3 AM incidents where someone rewrites the incident log four times before sending it to leadership.

Compliance Theater vs. Actual Security

Here’s where I’d normally expect things to get optimistic. Surely the industry has solved this by now. We have frameworks. Google’s SLSA (Supply-chain Levels for Software Artifacts) framework hit version 1.1 in 2025. It’s sophisticated. It’s well-designed. It actually works if you implement it properly. And yet. Fewer than 12 percent of major open-source projects have achieved even SLSA Level 1 compliance. Level one. The entry-level bar that basically says “you have some controls in place.” When I first saw that number, I had to read it three times. Because it meant that the projects most organizations depend on are operating at the trust-but-verify layer at best.

The problem is structural. Open-source maintainers are often overworked volunteers operating on the goodness of their hearts and the generosity of corporations using their work commercially. Asking them to implement supply chain security controls is like asking a charity to hire a full-time compliance officer. Theoretically correct. Practically impossible. So you end up with this weird equilibrium where the frameworks exist but adoption doesn’t follow. Enterprise organizations check the compliance box without understanding what they’re actually certifying. Maintainers ship code without the formal guarantees that would make distribution truly secure.

What Actually Matters Right Now

If you’re running production systems, you can’t wait for the industry to collectively fix itself. That’s not cynicism. That’s experience talking. You need to operate in the world as it exists, not as it should exist. Start by inventorying your dependencies like your career depends on it. Because it might. Understand every transitive dependency your code pulls in. Use tools that can actually see inside your supply chain instead of just surface-level scanning. Automate the boring parts so your team can focus on judgment calls instead of checkbox exercises.

The second part is harder but more important: assume something will get through. Your monitoring isn’t perfect. Your supply chain controls aren’t perfect. Your vendors aren’t perfect. So build detection at runtime. Implement runtime application self-protection. Segment your network so a compromised dependency doesn’t become a full infrastructure compromise. Use containerization isolation properly instead of treating it like a packaging convenience. Make it expensive for an attacker to convert a foothold into a breach.

The Real Problem Is Cultural

Technically, we know what needs to happen. Signed artifacts. Verified checksums. Reproducible builds. Transparent dependency trees. Automated compliance gates. Most of this technology exists and works. But between knowing what should happen and having it actually happen in production at scale is a chasm filled with budget constraints, competing priorities, and the eternal belief that “we’re probably fine.” CVE-2025-XXXXX is proof that we’re not fine. It’s the millionth proof at this point. And somehow the industry keeps acting surprised.

The uncomfortable truth is that supply chain security requires sustained investment from organizations that have other fires to put out. It requires maintainers to have resources they don’t have. It requires developers to slow down slightly to check what they’re pulling in. It requires DevOps teams to add friction to deployment pipelines. None of that is exciting. None of it shows up on a roadmap as a feature. But the alternative is accepting that every system you deploy has been compromised before it left the repository. At some point, that stops being acceptable.

What’s your current supply chain posture? I’m genuinely curious whether the teams reading this have implemented real controls beyond the compliance checklist. Drop a note in the comments or hit me on the socials. I’m collecting data on how actual organizations are responding to this shift, and I’d rather hear from people in the trenches than read another analyst report written by someone who hasn’t ssh’d into a production server since 2019.